Repository navigation
perf: speed up _unescape_special_chars for large documents #748
There are no files selected for viewing
| Original file line number | Diff line number | Diff line change |
|---|---|---|
|
|
@@ -2377,18 +2377,29 @@ def _encode_email_address(self, addr: str) -> str: | |
|
|
||
| def _unescape_special_chars(self, text: str) -> str: | ||
| # Swap back in all the special characters we've hidden. | ||
| if 'md5-' not in text: | ||
| return text | ||
| # Build hash→original mapping directly without intermediate tuple. | ||
| # html_blocks is stored inverted ({hash: item}) compared to the others. | ||
| replacements: dict[str, str] = {} | ||
| for ch, hash in self._escape_table.items(): | ||
|
Contributor
There was a problem hiding this comment. Would it be perhaps faster and simpler if instead of building a val = (
self._escape_table.get(match[0])
or self._code_table.get(match[0])
or self.html_blocks.get(match[0])
)Maybe more memory efficient?
Contributor
Author
There was a problem hiding this comment. That works for
Contributor
There was a problem hiding this comment. Ah yes, forgot about that. In that case building the map is probably the best way |
||
| replacements.setdefault(hash, ch) | ||
| for ch, hash in self._code_table.items(): | ||
| replacements.setdefault(hash, ch) | ||
| for hash, item in self.html_blocks.items(): | ||
| replacements.setdefault(hash, item) | ||
| # Scan once per nesting level. Use a flag instead of a full-string | ||
| # comparison to detect whether any replacement was made this pass. | ||
| while True: | ||
| replaced = [False] | ||
|
Contributor
There was a problem hiding this comment. Interesting but odd pattern. Would |
||
| def _sub(match: re.Match, _rep: dict = replacements) -> str: | ||
|
Contributor
There was a problem hiding this comment. Does
Contributor
There was a problem hiding this comment. Also
Contributor
Author
There was a problem hiding this comment. No, it doesn't. It uses
Contributor
Author
There was a problem hiding this comment. Good catch. It's defined once before the loop now, and only the flag is reset each pass (4bf3ddb). |
||
| val = _rep.get(match[0]) | ||
| if val is not None: | ||
| replaced[0] = True | ||
| return val | ||
| return match[0] | ||
| text = re.sub(r'md5-[0-9a-f]{32}', _sub, text) | ||
| if not replaced[0]: | ||
| break | ||
| return text | ||
|
|
||
|
|
||


There was a problem hiding this comment.
Choose a reason for hiding this comment
The reason will be displayed to describe this comment to others. Learn more.
Nitpick but I would remove the
→char in the comment in favour of plain text like->.I don't think it will cause any issues (python source is default utf-8) but I just think it can't be typed from a keyboard so should it be in a comment?
It also displays oddly in VSCode, really small and almost looks like an underline:
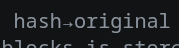
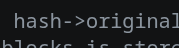
As opposed to this which is bigger and more legible:
There was a problem hiding this comment.
Choose a reason for hiding this comment
The reason will be displayed to describe this comment to others. Learn more.
Done in 4bf3ddb, it's plain
->now.